A model’s account of its reasoning and its actual reasoning are two different traces.
Richard J. Young · Alice M. Matthews — Divergence Lab, Lee Business School, University of Nevada, Las Vegas · deepneuro.ai
Abstract
Large language models produce fluent accounts of their own reasoning. Whether those accounts describe the computation that produced the answer is an open — and measurable — question. Divergence Lab measures the gap between what a model reports and what it does, using instruments adapted from experimental neuroscience. Current findings: safety behavior tracks surface form rather than principle [6]; reported reasoning diverges from answer behavior in open-weight reasoning models [1]; and the measurement itself is sensitive to the instrument doing the measuring [3]. None of this is academic: the same models are entering clinics, security workflows, and decision systems. Whether their reported reasoning can be trusted is a measurement question — so we build the instruments, and we release every one of them.
1 Introduction
Large language models produce artifacts that look like reasoning: fluent chains of steps, confident justifications, plausible accounts of how an answer was reached. The field’s default methodology is to ask the model to explain itself and treat the explanation as data. That assumption is empirically unsafe.
Neuroscience solved this methodological problem decades ago. In split-brain patients, the left hemisphere confidently narrates actions initiated by the right — actions it knows nothing about. The interpreter confabulates, fluently and without any signature of deception. The lesson was never “systems lie”; it was don’t ask the system — measure the gap between report and behavior. Instrument over interview.
Our standing finding is that models learn policies over surface forms rather than principles over acts: the same harmful request is refused as prose and complied with as executable code [6] [7]. Humans show the same signature — the Wason selection task is solved when framed as a social rule and failed in the abstract. Competence binds to representation, not content. Neither humans nor models generalize by principle; both respond to form. The difference is that we can take the model apart and ask why.
2 Methods
Every instrument in the lab has an ancestor in experimental psychology or neuroscience. We did not invent the methodology; we ported it.
Benchmark evaluation
Consensus-labeled stimulus banks presented under controlled surface-form variation; refusal thresholds measured per form, not per topic [6].
Abliteration
Removing a single direction in activation space. If prose-refusal survives while code-refusal collapses, the model holds two unlinked mechanisms — a double dissociation, in silicon [4].
3 Results
4 Publications
Curated, not exhaustive — twelve entries across the four research lines. The full record lives on the research page and CV.
AI + Safety
[1]Young, R. J. (2026). Why Models Know But Don't Say: Chain-of-Thought Faithfulness Divergence Between Thinking Tokens and Answers in Open-Weight Reasoning Models.arXiv:2603.26410[2]Young, R. J. (2026). Lie to Me: How Faithful Is Chain-of-Thought Reasoning in Reasoning Models?arXiv:2603.22582[3]Young, R. J. (2026). Measuring Faithfulness Depends on How You Measure: Classifier Sensitivity in LLM Chain-of-Thought Evaluation.arXiv:2603.20172[4]Young, R. J. (2025). Comparative Analysis of LLM Abliteration Methods: A Cross-Architecture Evaluation.arXiv:2512.13655[5]Young, R. J., & Matthews, A. M. (2026). EQUITRIAGE: A Fairness Audit of Gender Bias in LLM-Based Emergency Department Triage.arXiv:2605.03998AI + Cybersecurity
[6]Young, R. J., & Moody, G. D. (2026). A Validated Prompt Bank for Malicious Code Generation: Separating Executable Weapons from Security Knowledge in 1,554 Consensus-Labeled Prompts.arXiv:2605.03179[7]Young, R. J., & Moody, G. D. (2026). Refusal Evaluation in Coding LLMs and Code Agents: A Systematic Review of Thirteen Malicious-Code Prompt Corpora (2023–2025).arXiv preprint[8]Young, R. J. (2025). Evaluating the Robustness of Large Language Model Safety Guardrails Against Adversarial Attacks.arXiv:2511.22047[9]Young, R. J. (2025). Replicating TEMPEST at Scale: Multi-Turn Adversarial Attacks Against Trillion-Parameter Frontier Models.arXiv:2512.07059AI + Clinical Care
[10]Young, R. J., & Matthews, A. M. (2025). CardioEmbed: Domain-Specialized Text Embeddings for Clinical Cardiology.arXiv:2511.10930[11]Young, R. J. (2025). Vision Token Masking Alone Cannot Prevent PHI Leakage in Medical Document OCR: A Systematic Evaluation.arXiv:2511.18272[12]Young, R. J., Matthews, A., & Poston, B. (2025). Benchmarking Multiple Large Language Models for Automated Clinical Trial Data Extraction in Aging Research.AlgorithmsAI + Production
[13]Young, R. J., Gillins, B., & Matthews, A. M. (2025). When Models Can't Follow: Testing Instruction Adherence Across 256 LLMs.arXiv:2510.18892[14]Young, R. J., & Matthews, A. M. (2025). Comparative Analysis of LoRA-Adapted Embedding Models for Clinical Cardiology Text Representation.arXiv:2511.197395 Join
You can run a real experiment in fifteen weeks. This work parallelizes unusually well: a single model family, a single stimulus set, a single replication — each is a self-contained study that composes into a paper. If you can write Python and read a results table honestly, you can contribute.
The lab takes a couple of students a year, total. Focus is the operating principle: fewer people, real advising time, and a finished artifact per person.
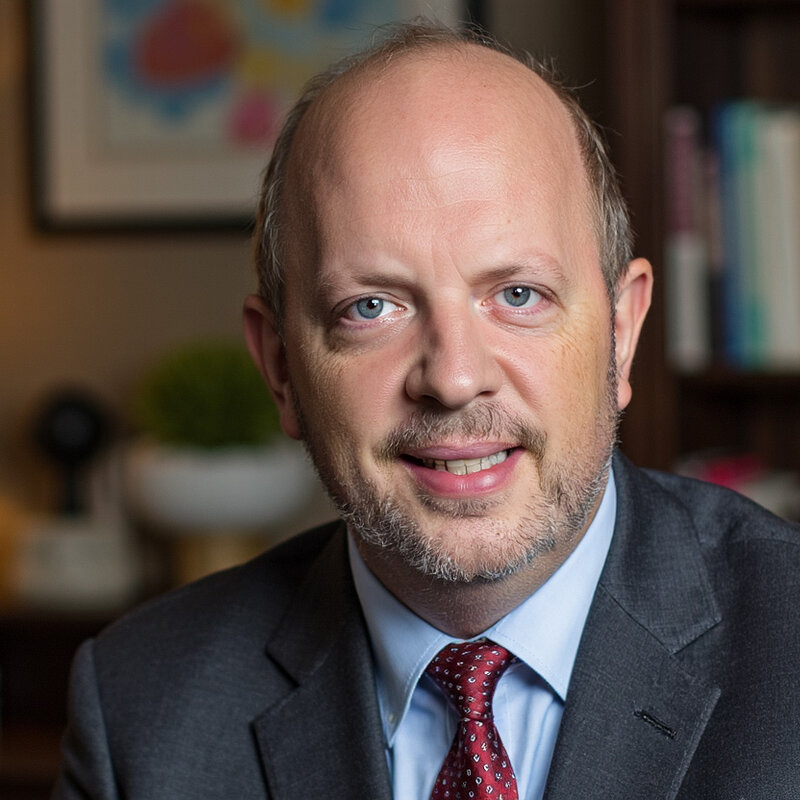 Richard J. Young, Ph.D.Principal Investigator
 Alice Matthews, Ph.D., RDCSResearch Scientist
 LuckyLab Mascot
- Open to MS Data Analytics, MIS, and capstone students at UNLV
- Authorship on what you produce — not a line in the acknowledgments
- No IRB delay: model evaluation isn’t human-subjects research, so you start in week one
- You’ll leave with a public artifact — a dataset, a benchmark, or a preprint with your name on it
Notes added in proof